Version checked for this guide: 1.0.12 · 2026-09-23
Begin with a validated mass_dataset and sample classes, batches and injection order. Filter excessive missingness before imputation. Review outlier candidates with experimental records, rather than automatically deleting every unusual PCA sample.
impute_mv() offers kNN, random forest, simple-value and model-based methods. Choose the method and sample subset based on the missingness mechanism and data size. normalize_data() provides sample-wise total, mean, median and PQN methods and QC-based SVR/LOESS. QC correction needs suitable QC coverage and acquisition metadata. integrate_data() and align_batch() address supported cross-batch tasks; they do not resolve a design in which batch and biological group are completely confounded.
Preserve the input object, inspect missingness and QC metrics afterwards and compare before/after plots. For predictive modeling, fit preprocessing within each training fold to avoid leakage. The example uses median imputation and median normalization only to illustrate the API.
Visual guide: the route through this chapter
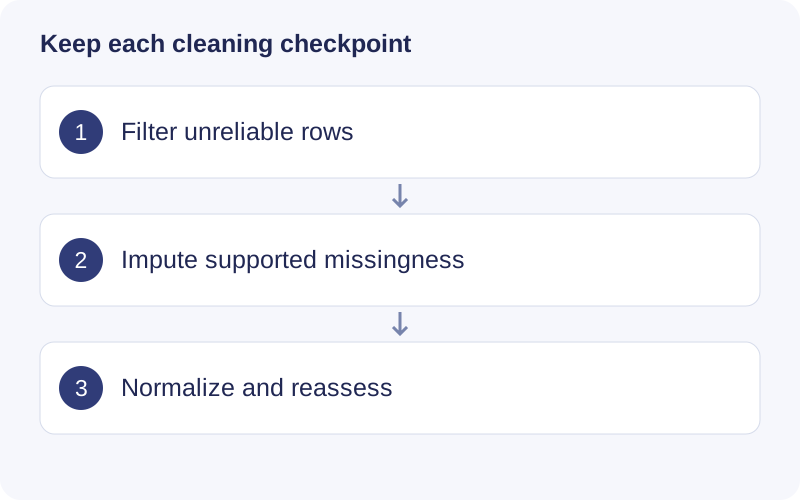
Save the unmodified object first. Inspect which rows fail your missingness rule, then impute only the retained data. Compare intensity distributions and QC behavior after normalization. Document the method and excluded IDs; never treat imputed values as independently observed peaks.
Functional scope
Outlier detection and reporting; missing-value imputation; sample-wise/QC-based normalization; LOESS optimization; batch alignment and integration.
Example
# object is the mass_dataset created/imported in the previous chapter.
expr <- massdataset::extract_expression_data(object)
keep <- which(rowSums(!is.na(expr)) > 0)
stopifnot(length(keep) > 0)
object <- object[keep, ]
cleaned <- masscleaner::impute_mv(object, method = "median")
normalized <- masscleaner::normalize_data(cleaned, method = "median")
saveRDS(normalized, "normalized.rds")
Find a function
The checked source exports the following APIs, including compatibility interfaces and utilities. Consult the installed version with help("function_name", package = "masscleaner") for argument details.
Show exported functions
align_batch, check_for_data_integration, check_for_qc_normalization, detect_outlier, extract_outlier_table, get_masscleaner_version, impute_mv, integrate_data, masscleaner_conflicts, masscleaner_logo, masscleaner_packages, normalize_data, normalize_data_pqn, optimize_loess_span
Package source and reference documentation · Complete workflow
Walkthrough: Compare intensity distributions
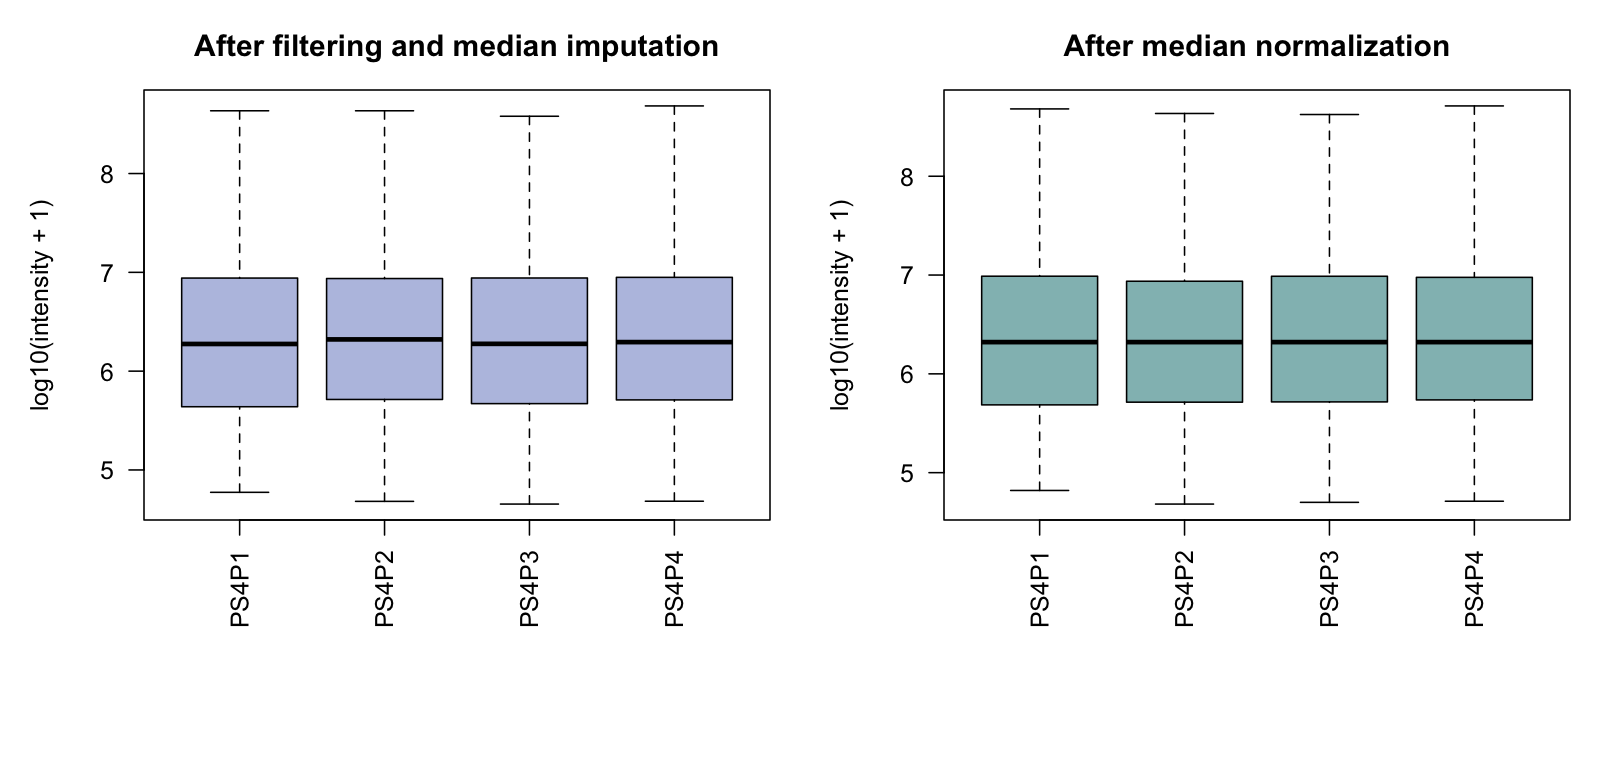
- Both panels plot log10(intensity + 1) for display; the left input is already filtered and imputed.
- The right panel follows median normalization. Similar medians are an expected consequence of this method, not independent proof that technical bias is removed.
- Check study design and quantitative QCs where available before choosing normalization for real data.